

Abnormal classifies billions of emails a week, and in this post we test how decision models hold up against the recent hype, using our own non-public email security data.
Our production models are behavioral, learning what normal looks like for each sender, recipient, and organization from signals like sender history, authentication, and the org directory. Deciding whether that request makes sense between this sender and this recipient takes understanding the text itself and knowing how businesses normally operate, like whether a vendor would really change bank details in the middle of an invoice thread. A model built on engineered features only sees the signals it was given. An LLM has learned language and that kind of everyday business knowledge from pretraining, so it can read the request the way an analyst would, with the same behavioral signals as context
Decision models (often) read the email and every question in one forward pass and return a probability for each option without generating a token, so an answer costs about what it costs to read the input. We think that makes LLM-class judgment cheap and fast enough to deploy at far larger scale, behind the right prefilters. Each question is also written in plain language, so a new detector can start zero-shot as a written question rather than a feature to build and a model to retrain.
We tested TypeSafe’s Jev, the OpenAI Decisions API, 34 open decision models we self-hosted, and four frontier LLM configurations (40 models in all)1, then fine-tuned one of the small open models ourselves.
Experimental setup
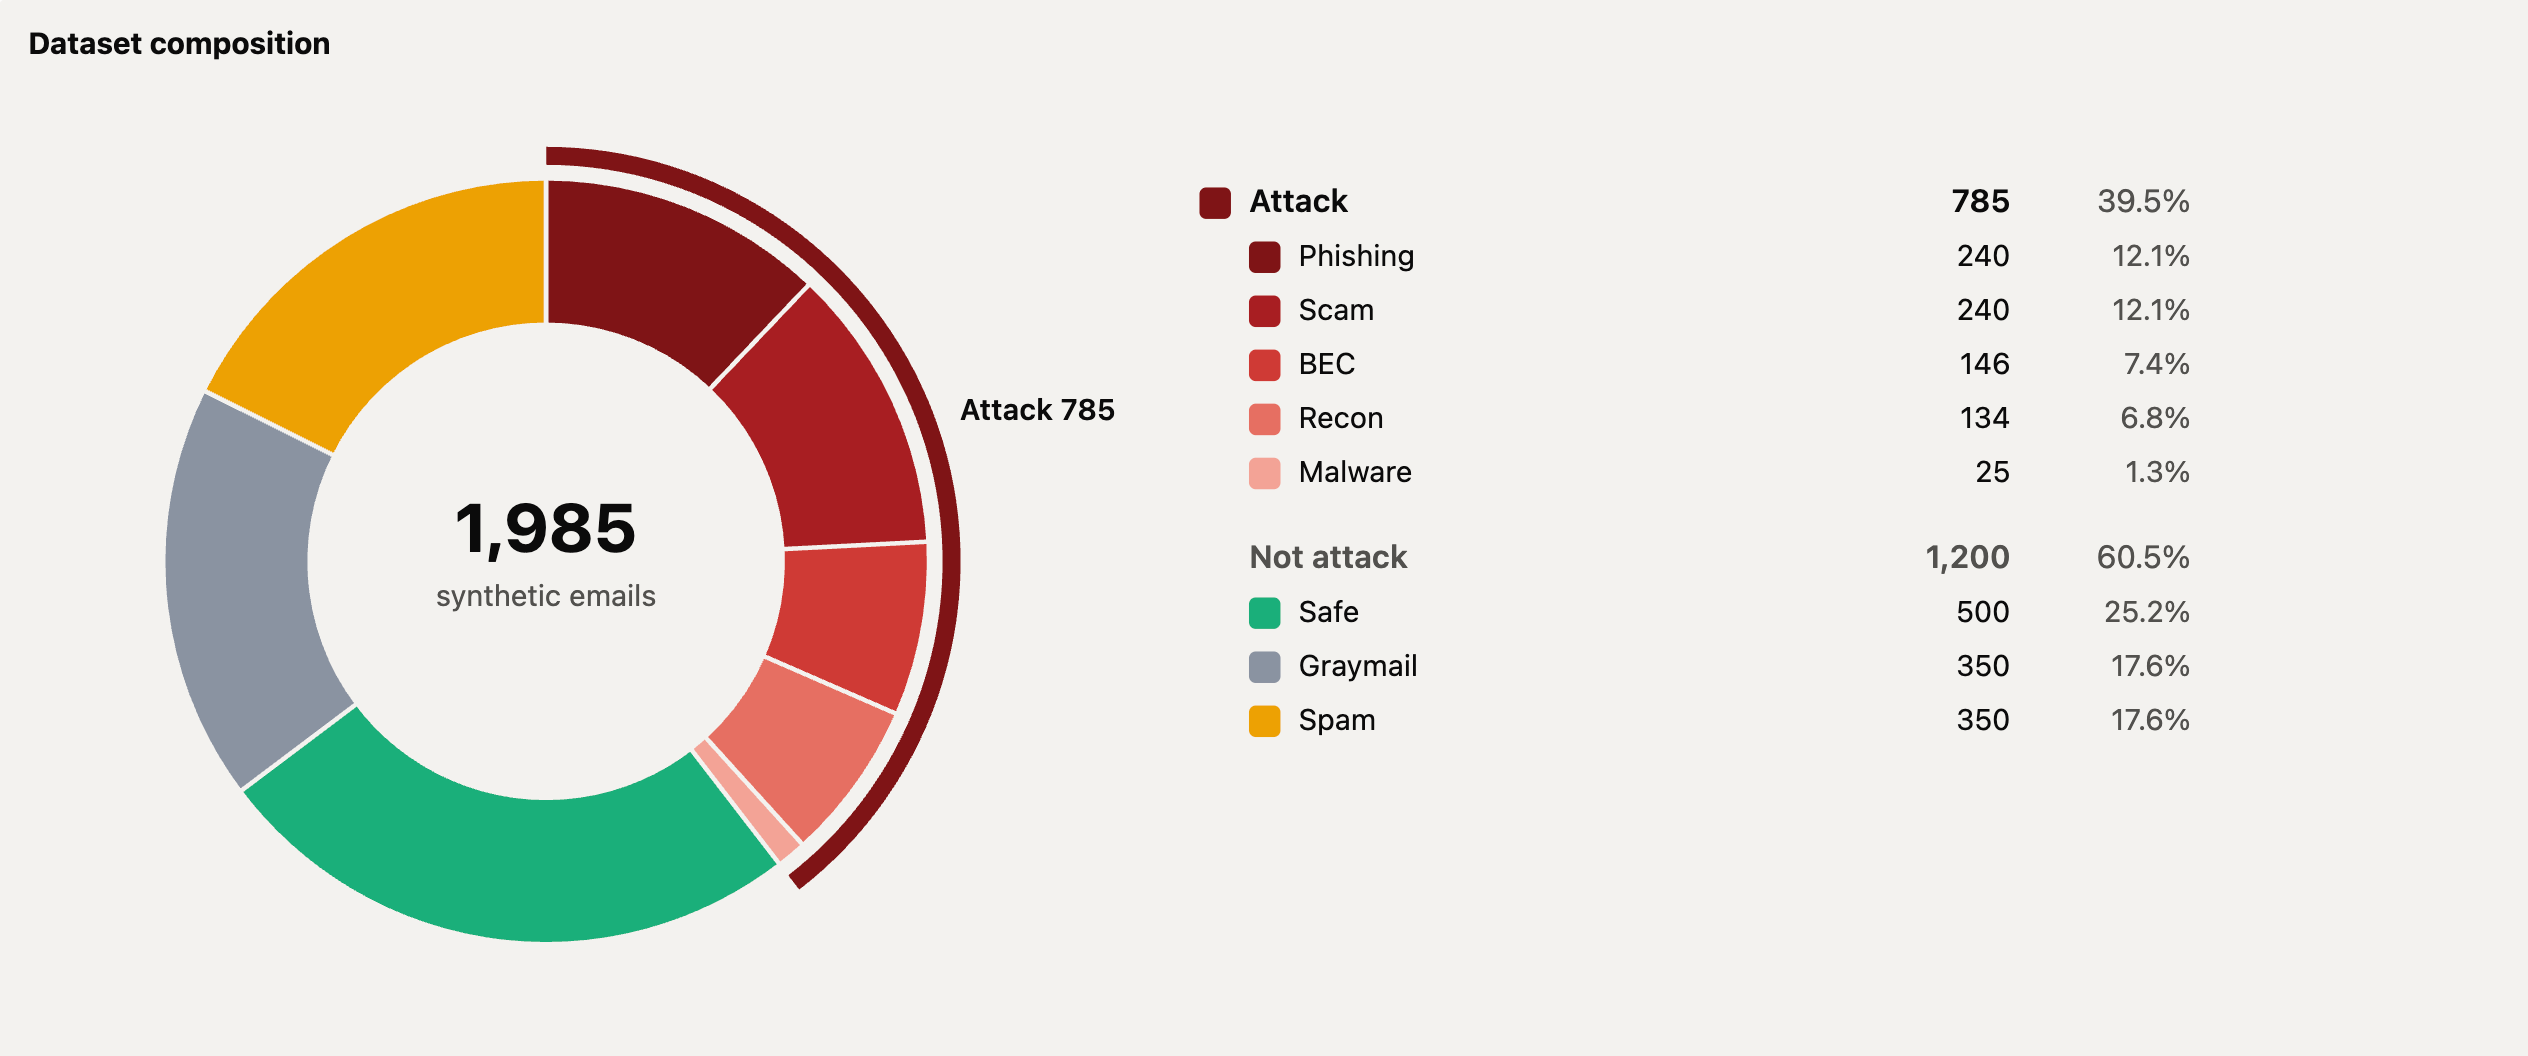
The dataset is 1,985 non-public, fully synthetic emails with no customer data, modeled on the hard cases we see in production (attacks and the tricky false positives that look like them). Rather than prompting a model to write a phishing email, we generated each one to match the class, attack type, and detection signals of a real hard case without reusing its identifiers.
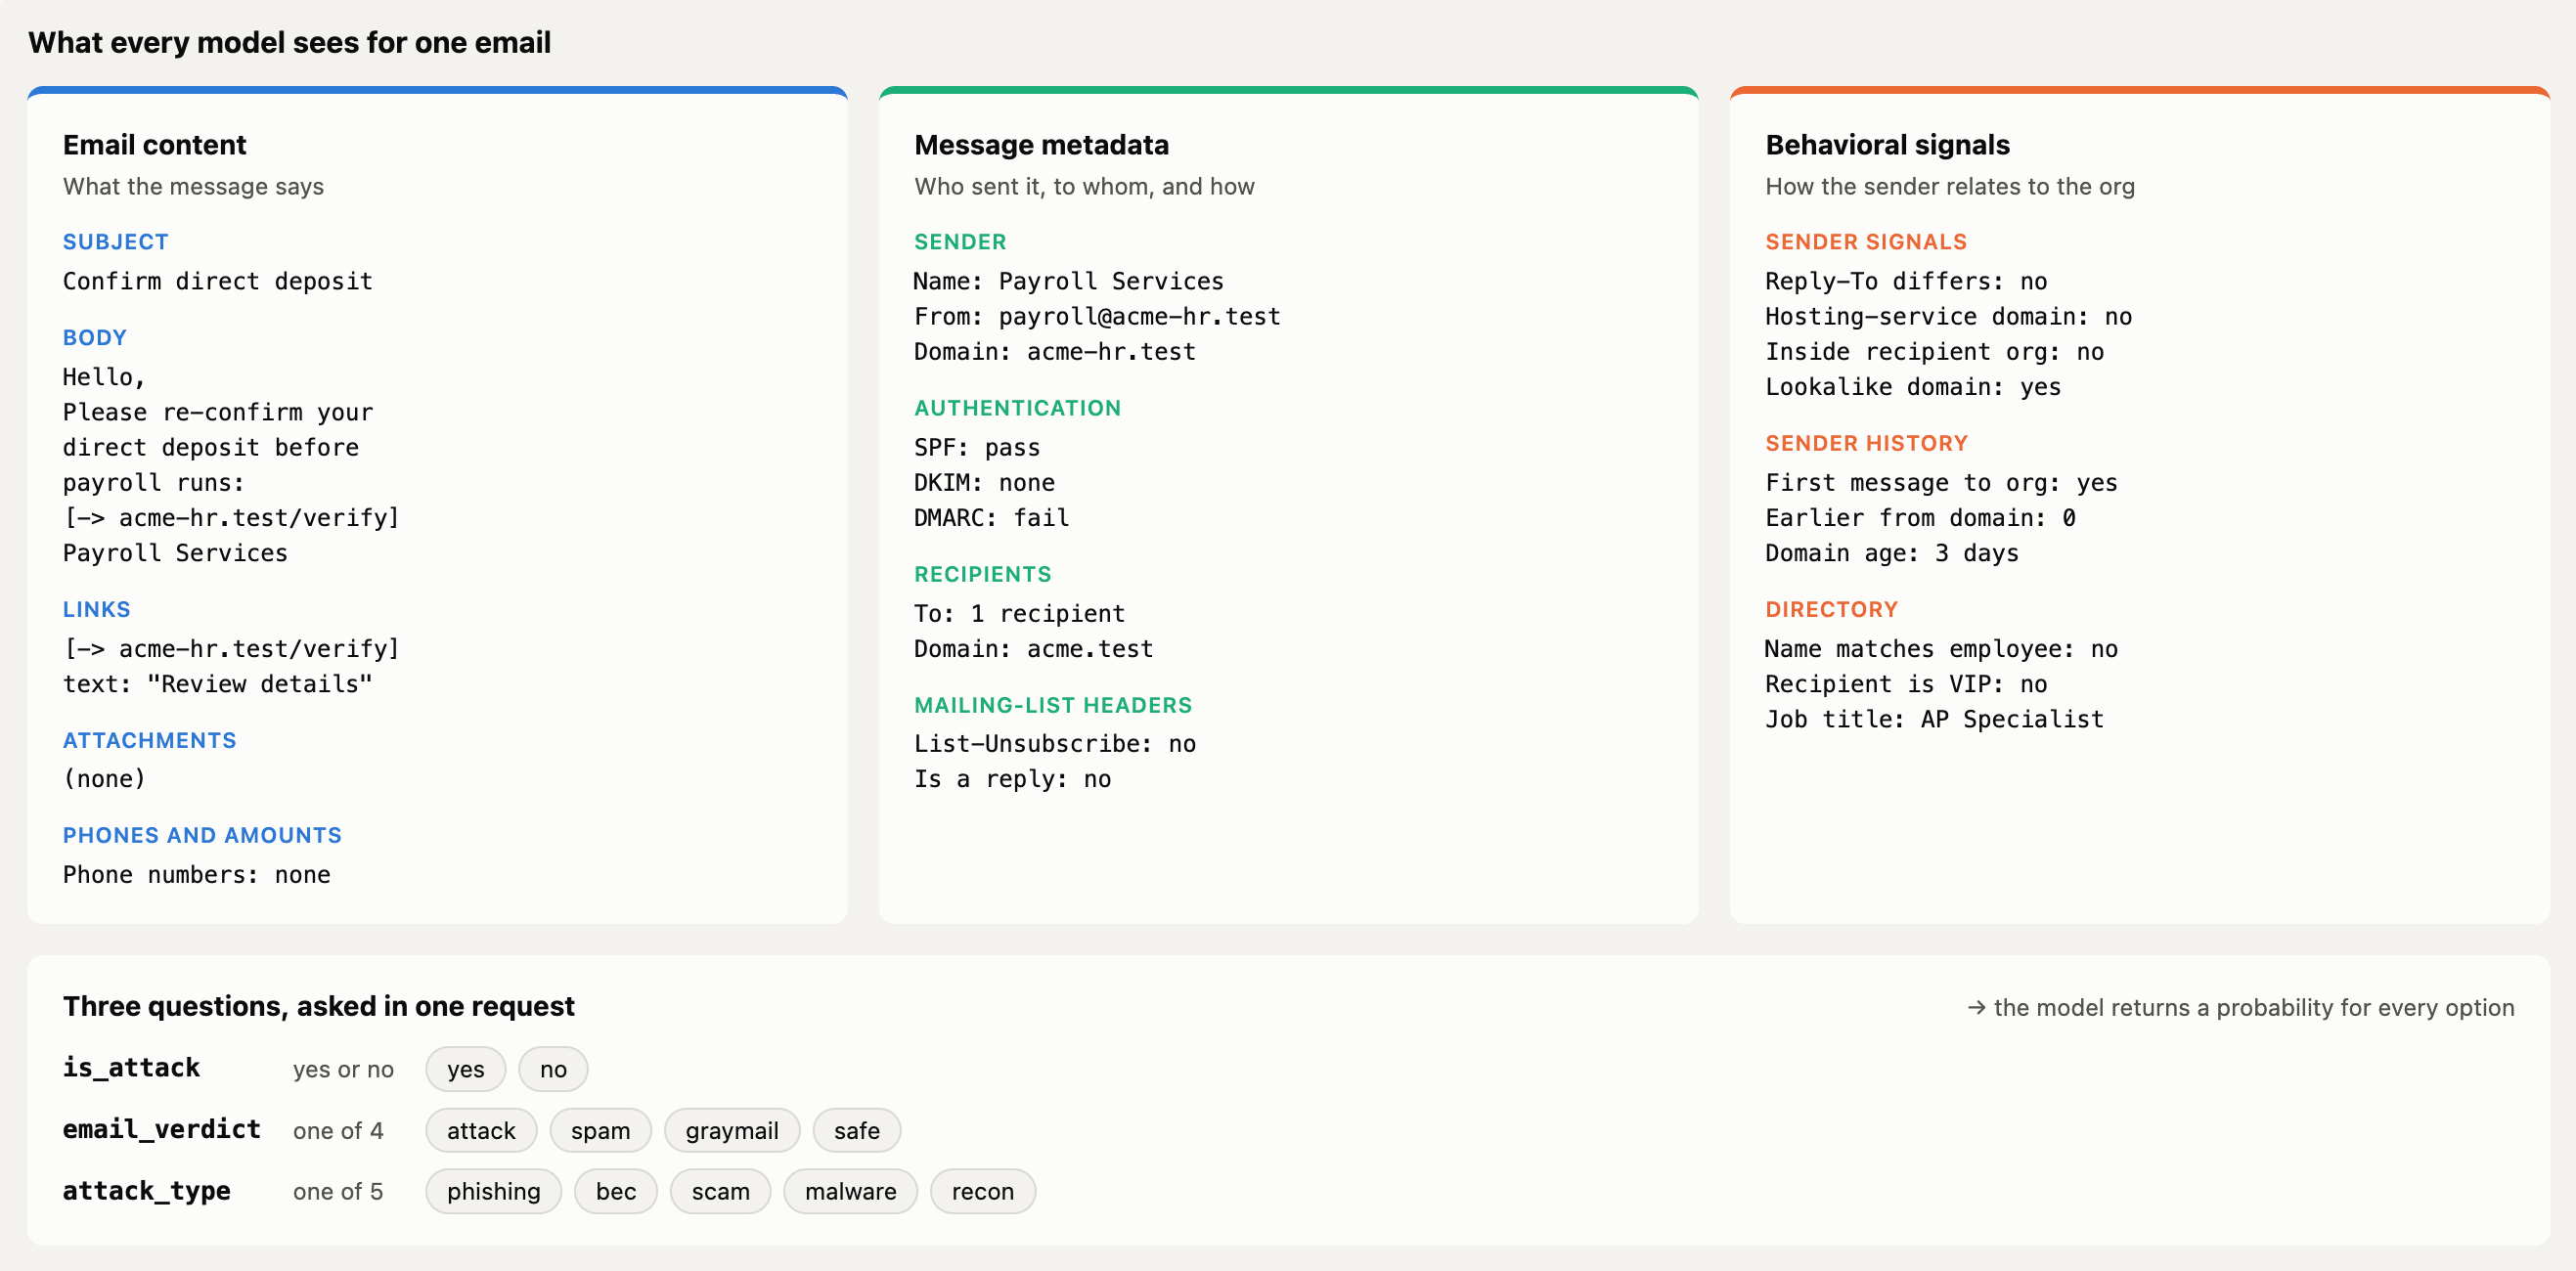
Every model gets the same email, rendered as the fields an email security system extracts, and answers three questions in one request: is it an attack (yes or no), what kind of mail is it (attack, spam, graymail, or safe), and for attacks, which type (phishing, BEC, scam, malware, or recon). Decision models read the record natively, while LLMs get it as JSON and have to return a probability for every option under a strict schema.
To rank models on one number, we use an email score, defined as 100 × the mean of verdict macro-F1, attack-type macro-F1, and attack recall at 95% precision. The terms track three jobs a detection system does (sorting the mail, naming the attack, and catching attacks while keeping false alarms rare). Macro-F1 counts rare classes like malware as much as common ones, and the equal weights mean no model scores well by acing just one job2.
Results
Efficacy at Cost
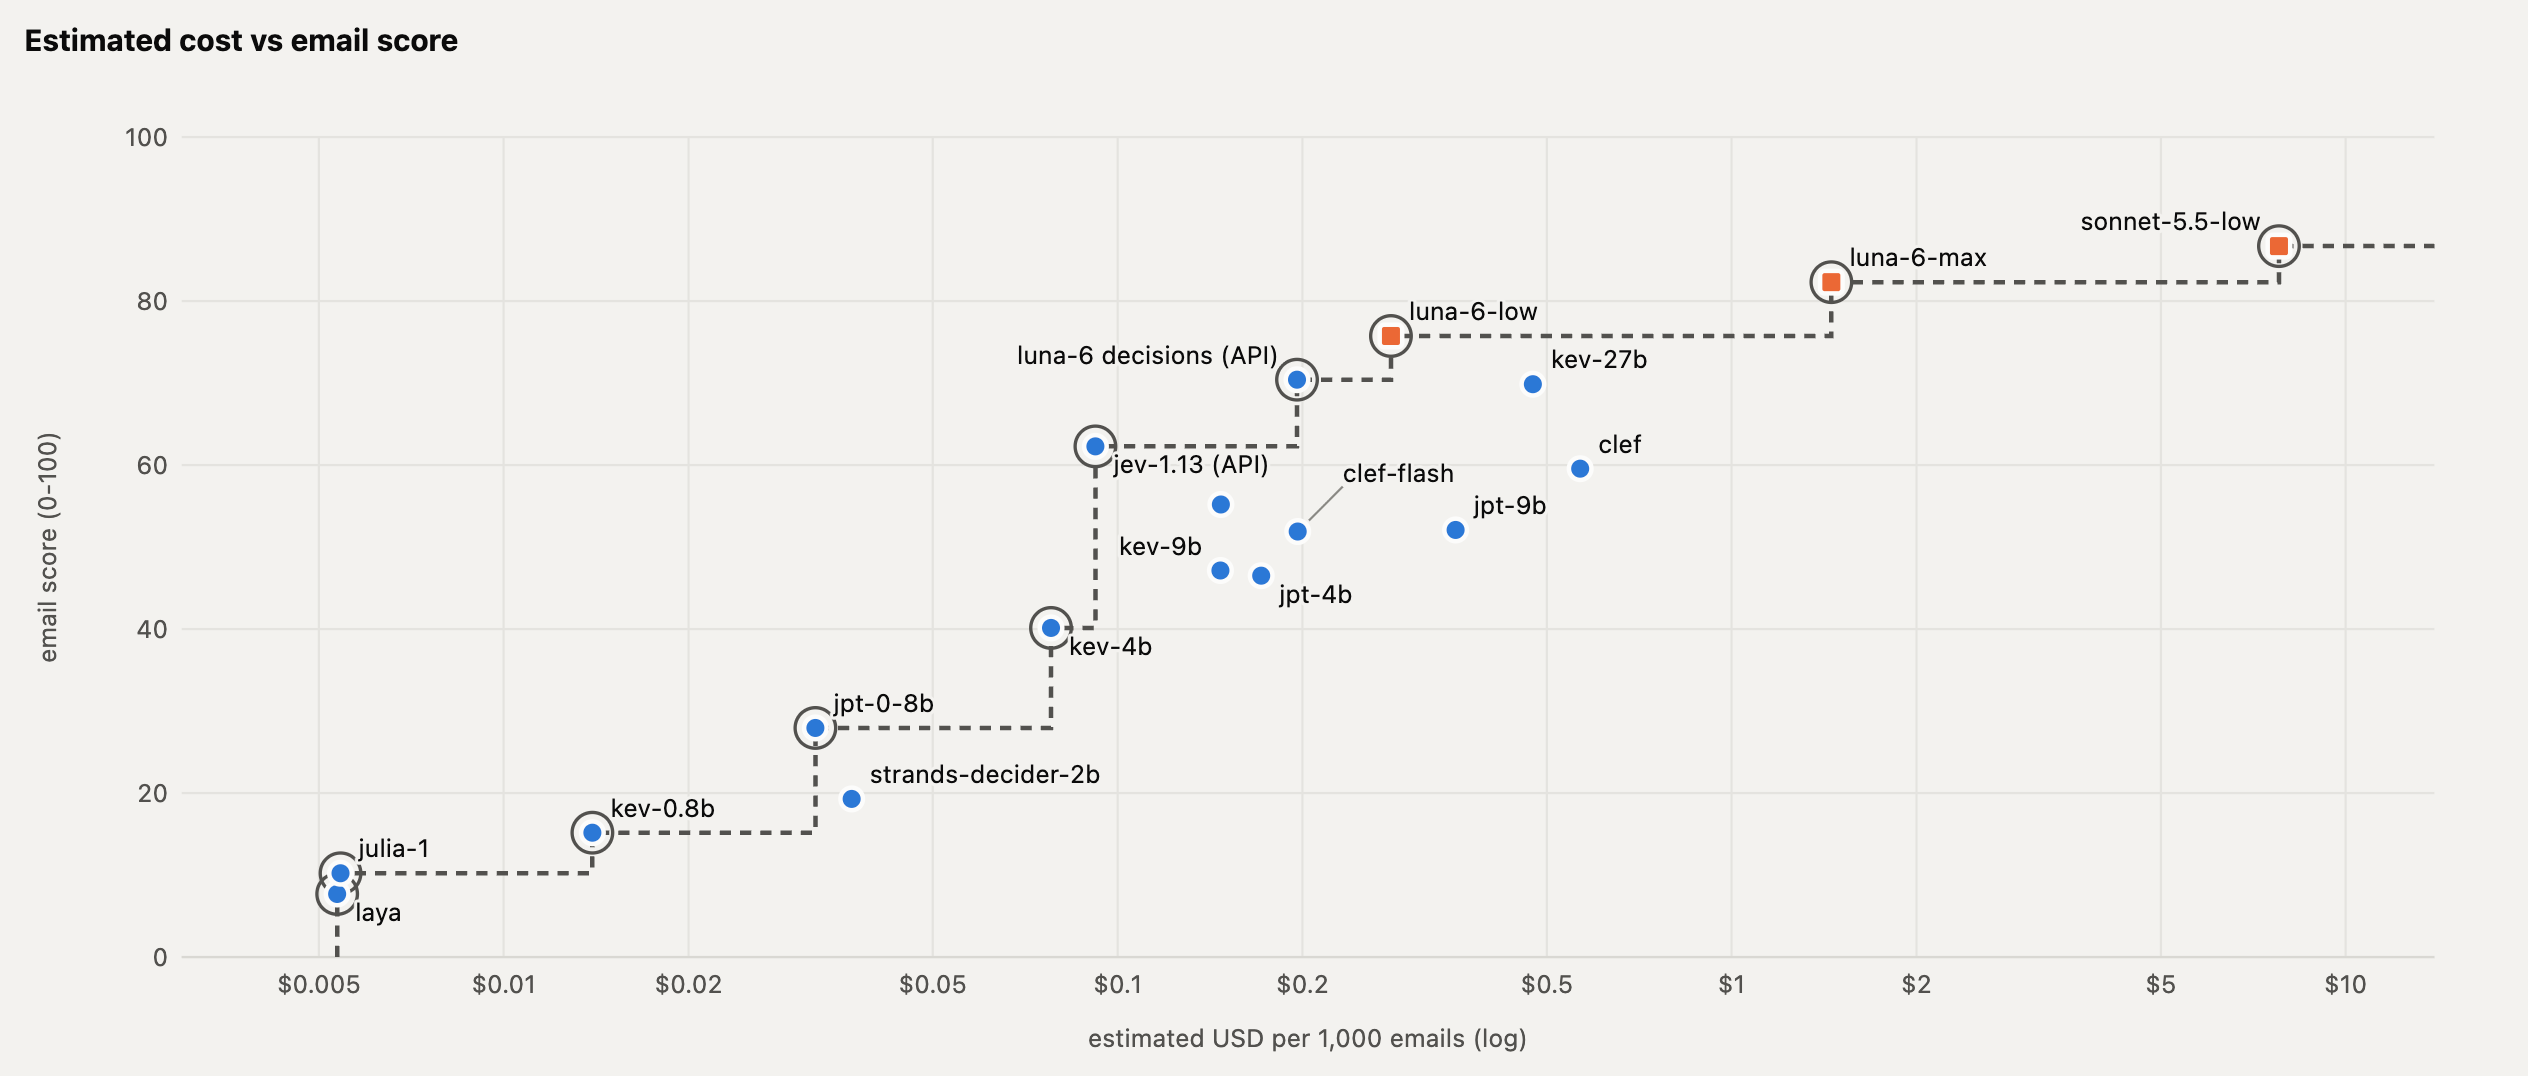
On cost versus the composite email score, larger models generally score higher and the frontier LLMs lead. Those gains are rarely cost-effective, though, since each step up the curve costs far more than the one before it. Jev and the OpenAI Decisions API both sit on the Pareto frontier, scoring well above the open models at their price3.
Efficacy at High Precision
In email security, the composite score isn’t what decides whether a model is usable. When a model calls an email an attack, we pull it from the inbox, so every false positive is a legitimate and often important email that a customer never sees. Precision is the constraint and recall is the prize, so we look at each model’s precision-recall curve and read off how many attacks it catches at 99% precision.
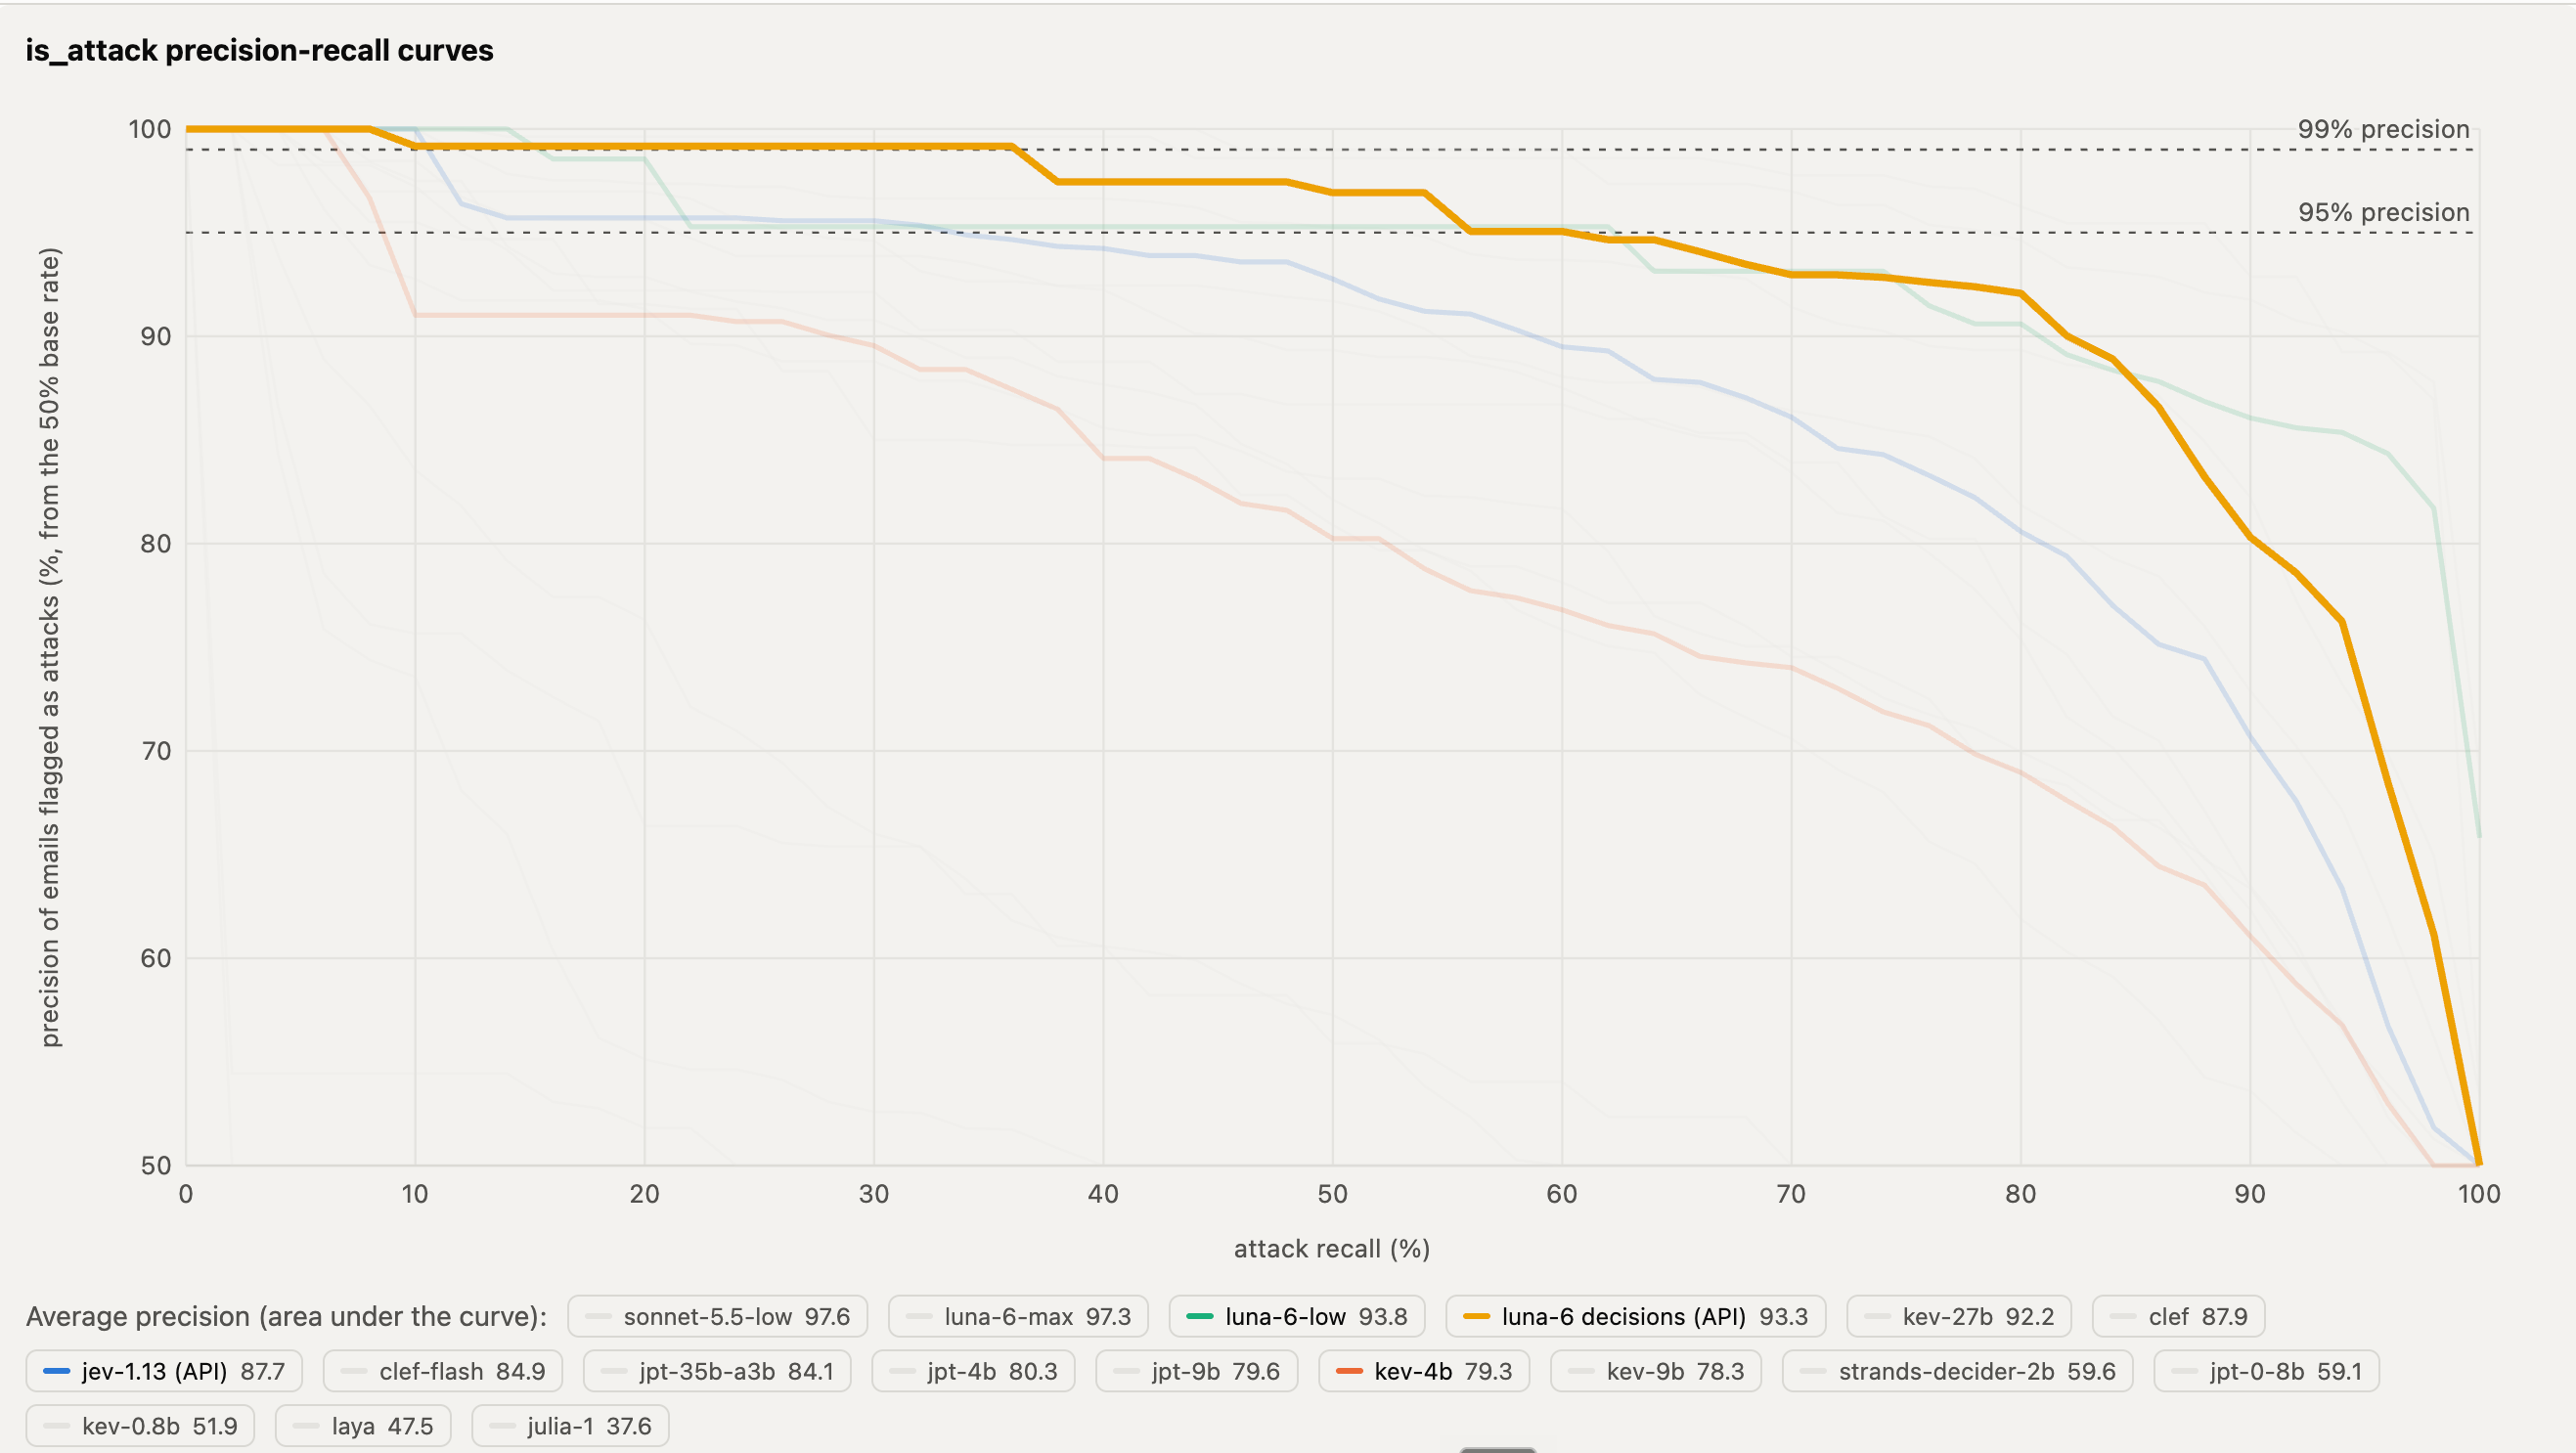
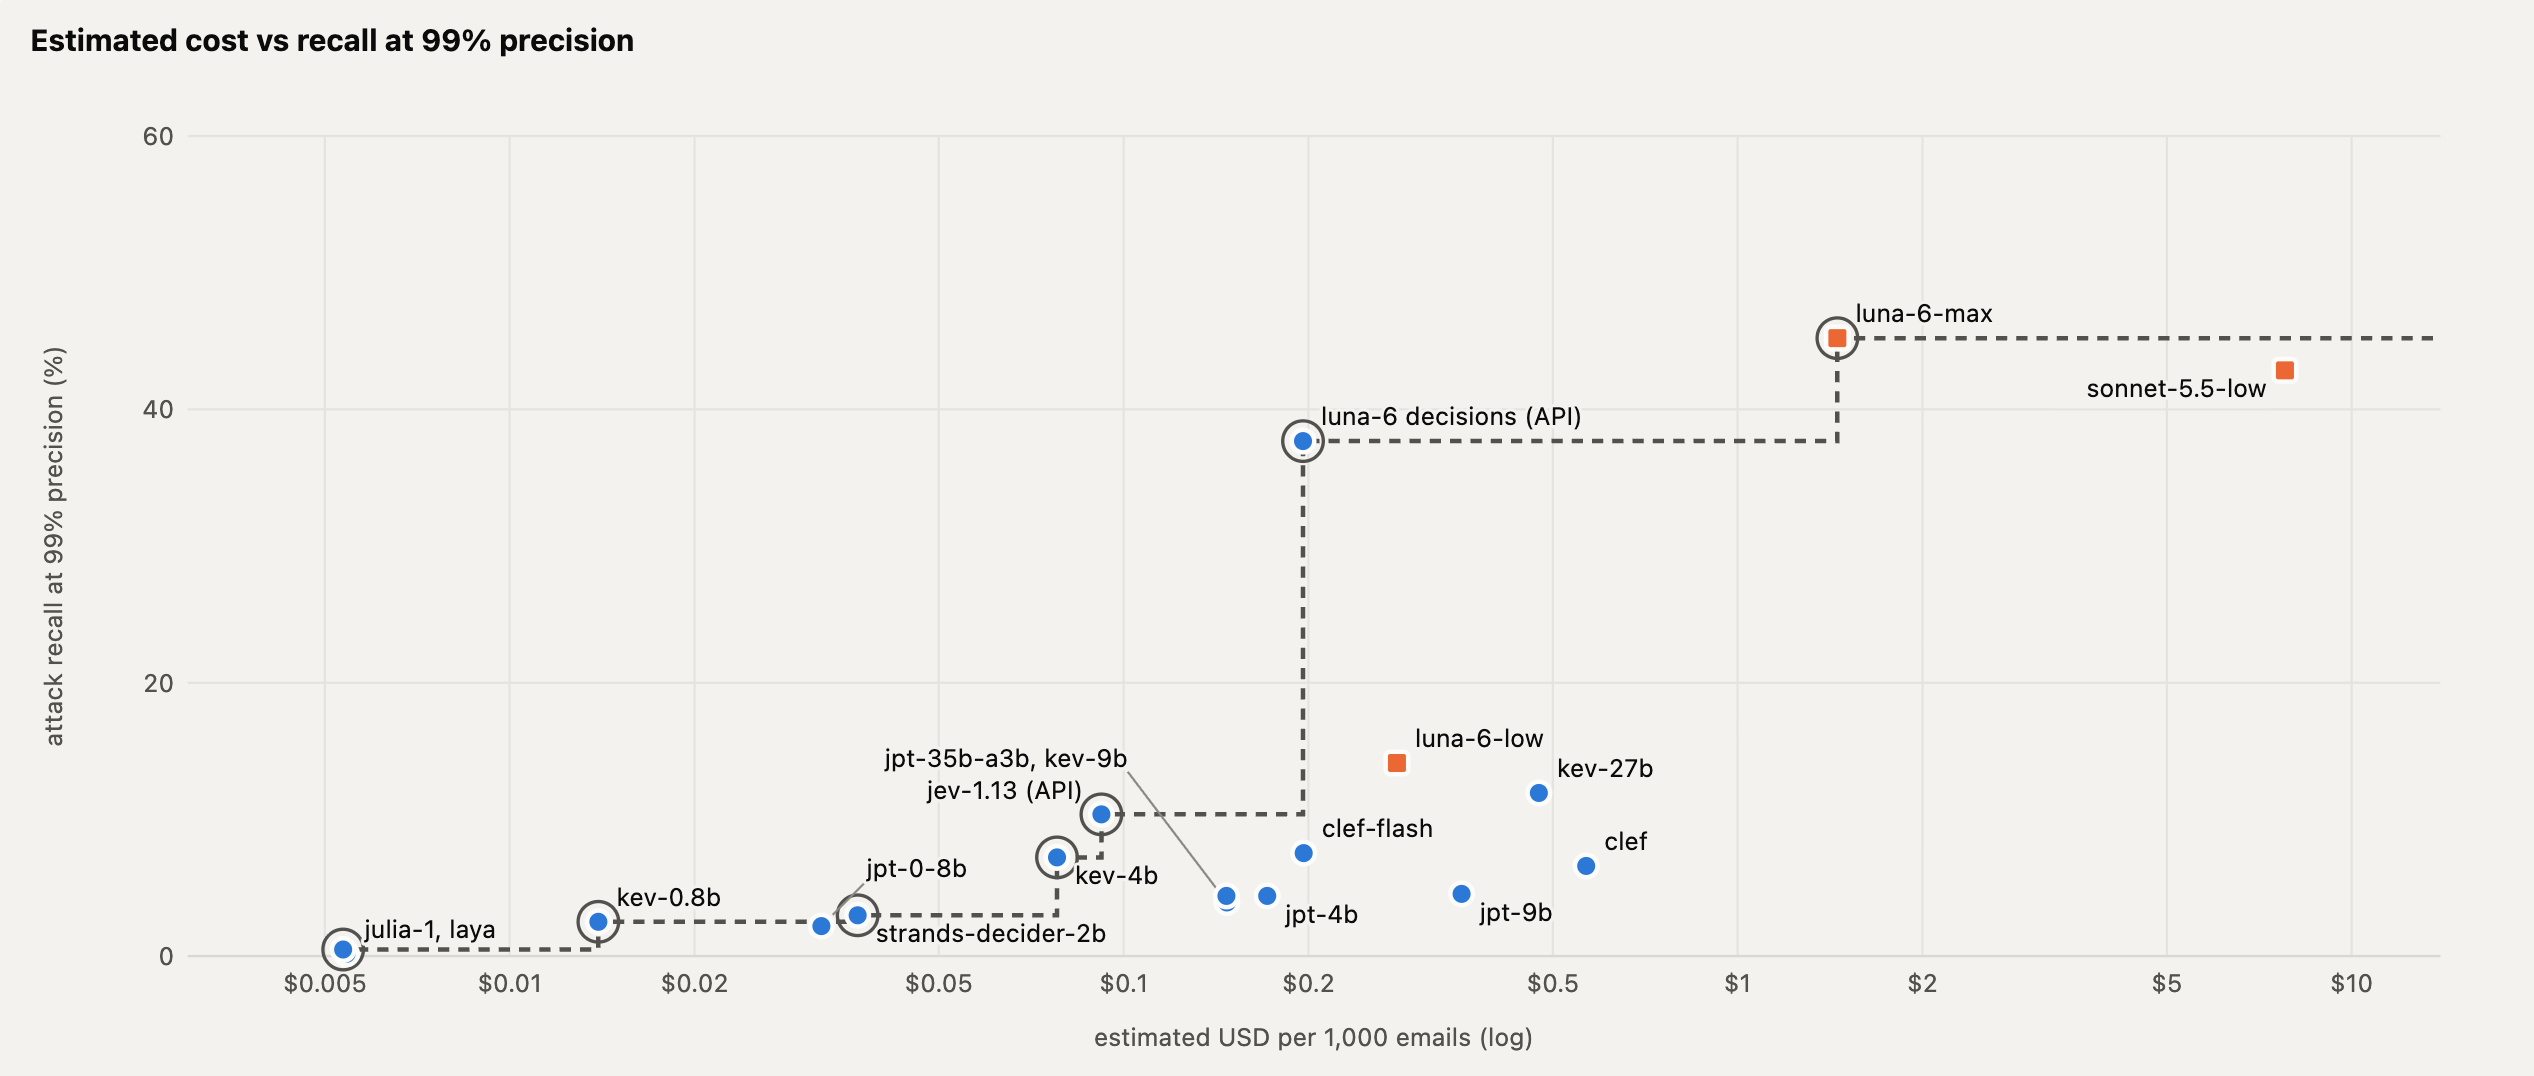
Against cost, recall at 99% precision collapses the frontier to a handful of models. Most of the field, including every open model we self-hosted, catches only a small fraction of attacks, and Jev stays on the frontier on price alone. The OpenAI Decisions API is the standout, catching most of what luna-6-max does at a fraction of the cost and latency. The most instructive miss is luna-6-low, the same luna-6 model prompted as an LLM. It matches the Decisions API on average precision but falls far behind at 99% precision, because threshold-free metrics hide the part of the curve you actually operate in.
Calibration
Security systems often act on the probability, not just the label. Above one threshold an email is remediated automatically, a middle band goes to review, and everything below is delivered. Those thresholds have to keep meaning the same thing across tenants and model upgrades, and the probability is also what lets one detector's output be combined with others or weighed against the cost of a miss. All of that only works if a stated 0.9 means about 90% of those emails really are attacks.
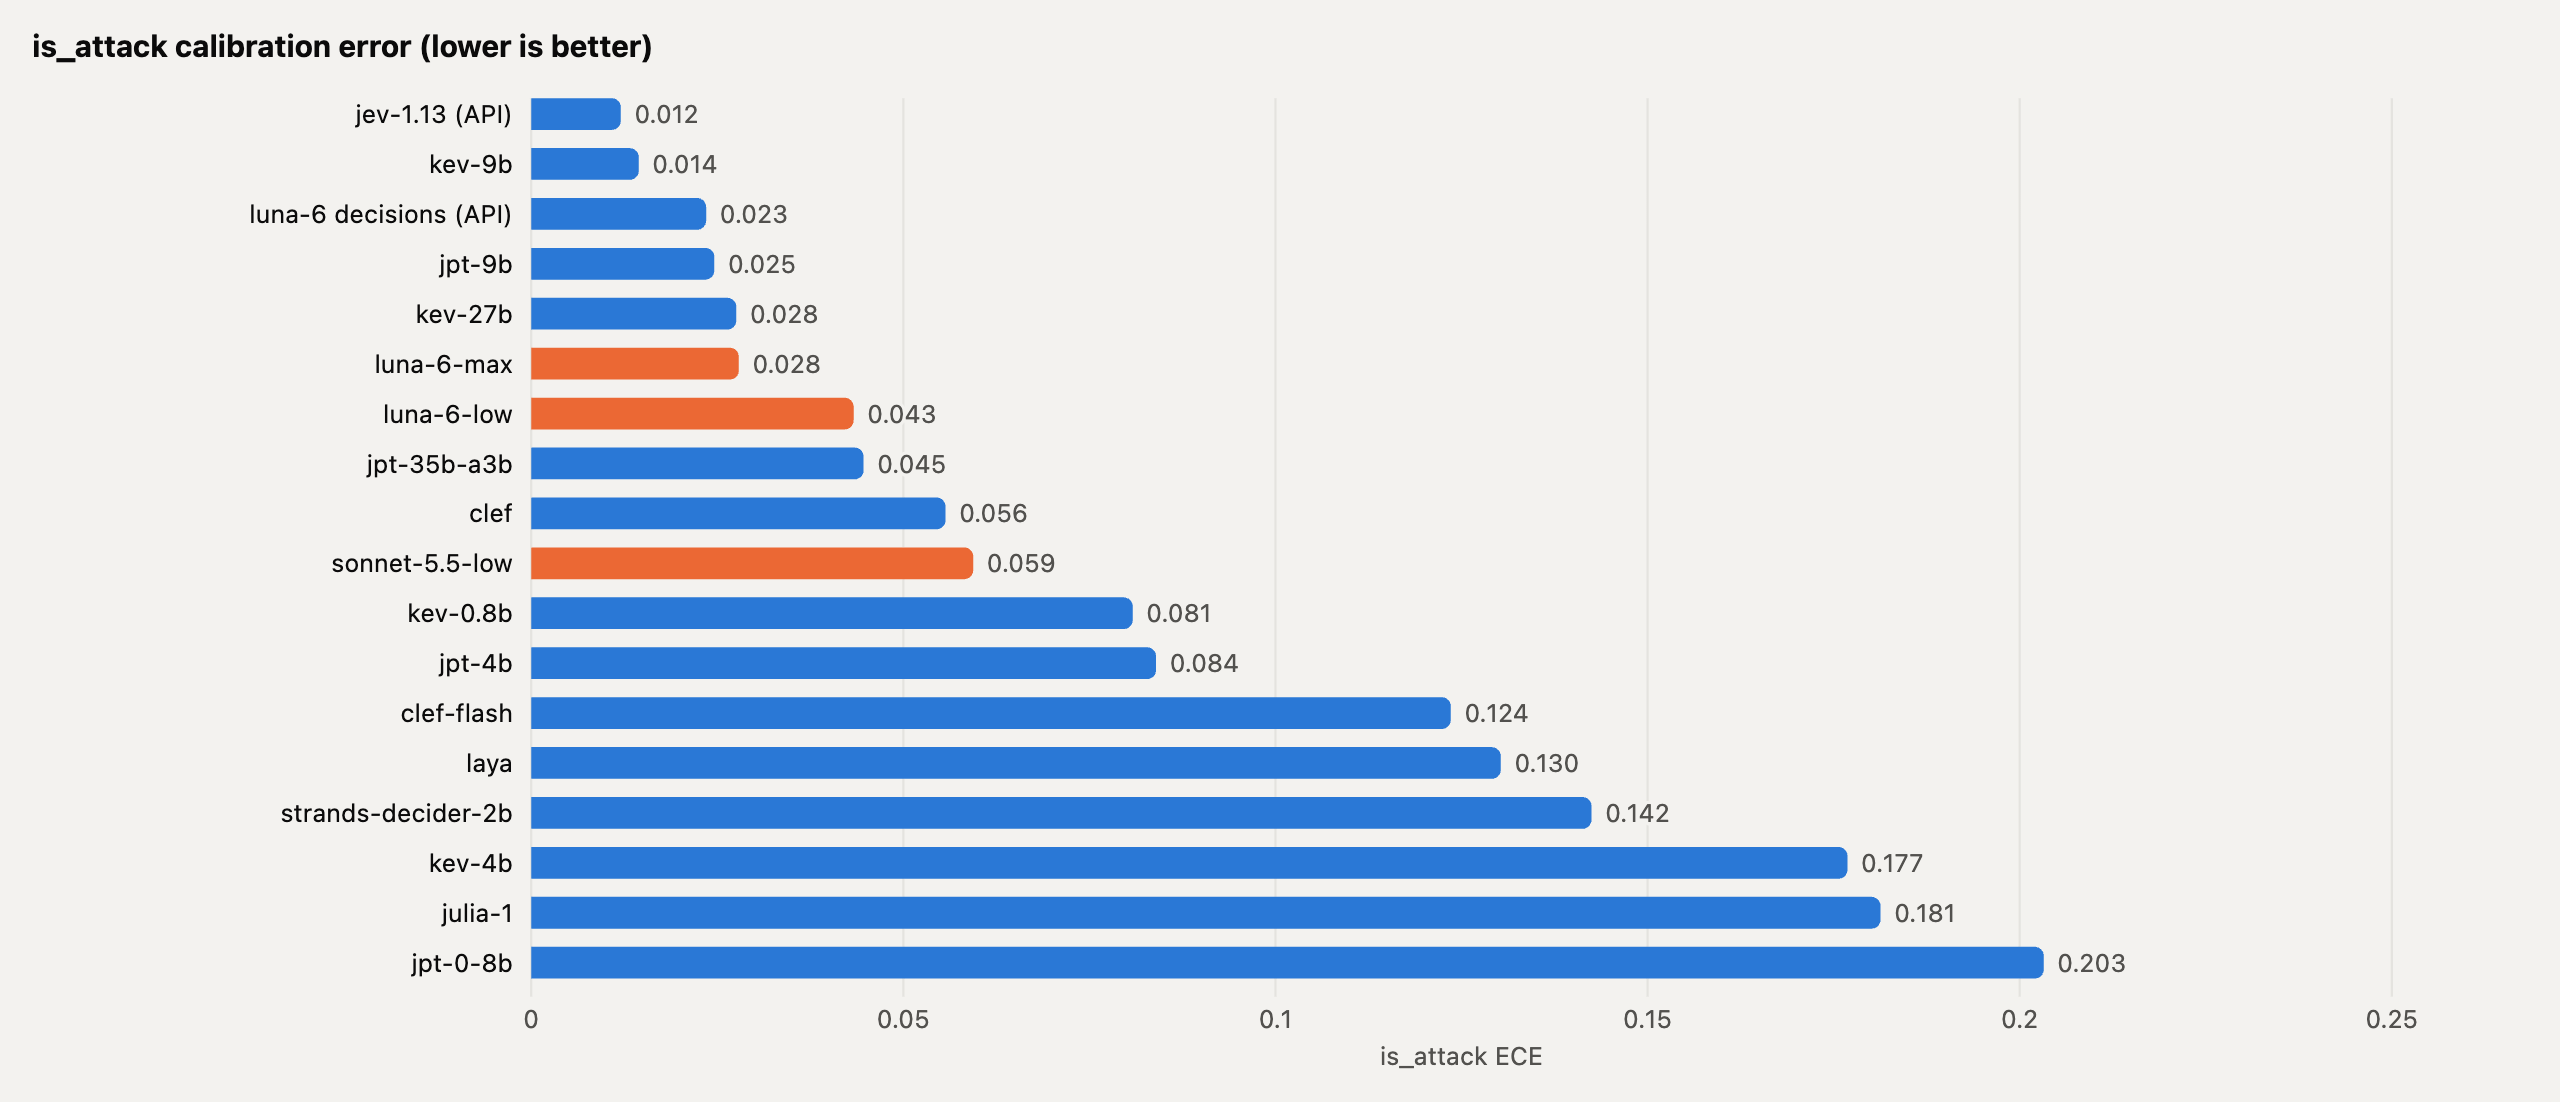
The decision APIs come back among the best calibrated, with Jev the best calibrated of any model we tested. The frontier LLMs land in the middle even when the prompt asks them directly for honest, calibrated probabilities. The small open decision models are the worst, base kev-4b among them, so calibration depends on the model rather than the interface.
Finetuning Kev-4B
As an experiment, we fine-tuned kev-4b on a variety of email and non-email classification tasks, a single-epoch LoRA run over 60K examples that cost about $200 on L40S GPUs. Nothing in training overlaps with this benchmark in either emails or task format, since the benchmark’s synthetic emails were never trained on and its text encoding and question wording differ from ours4.
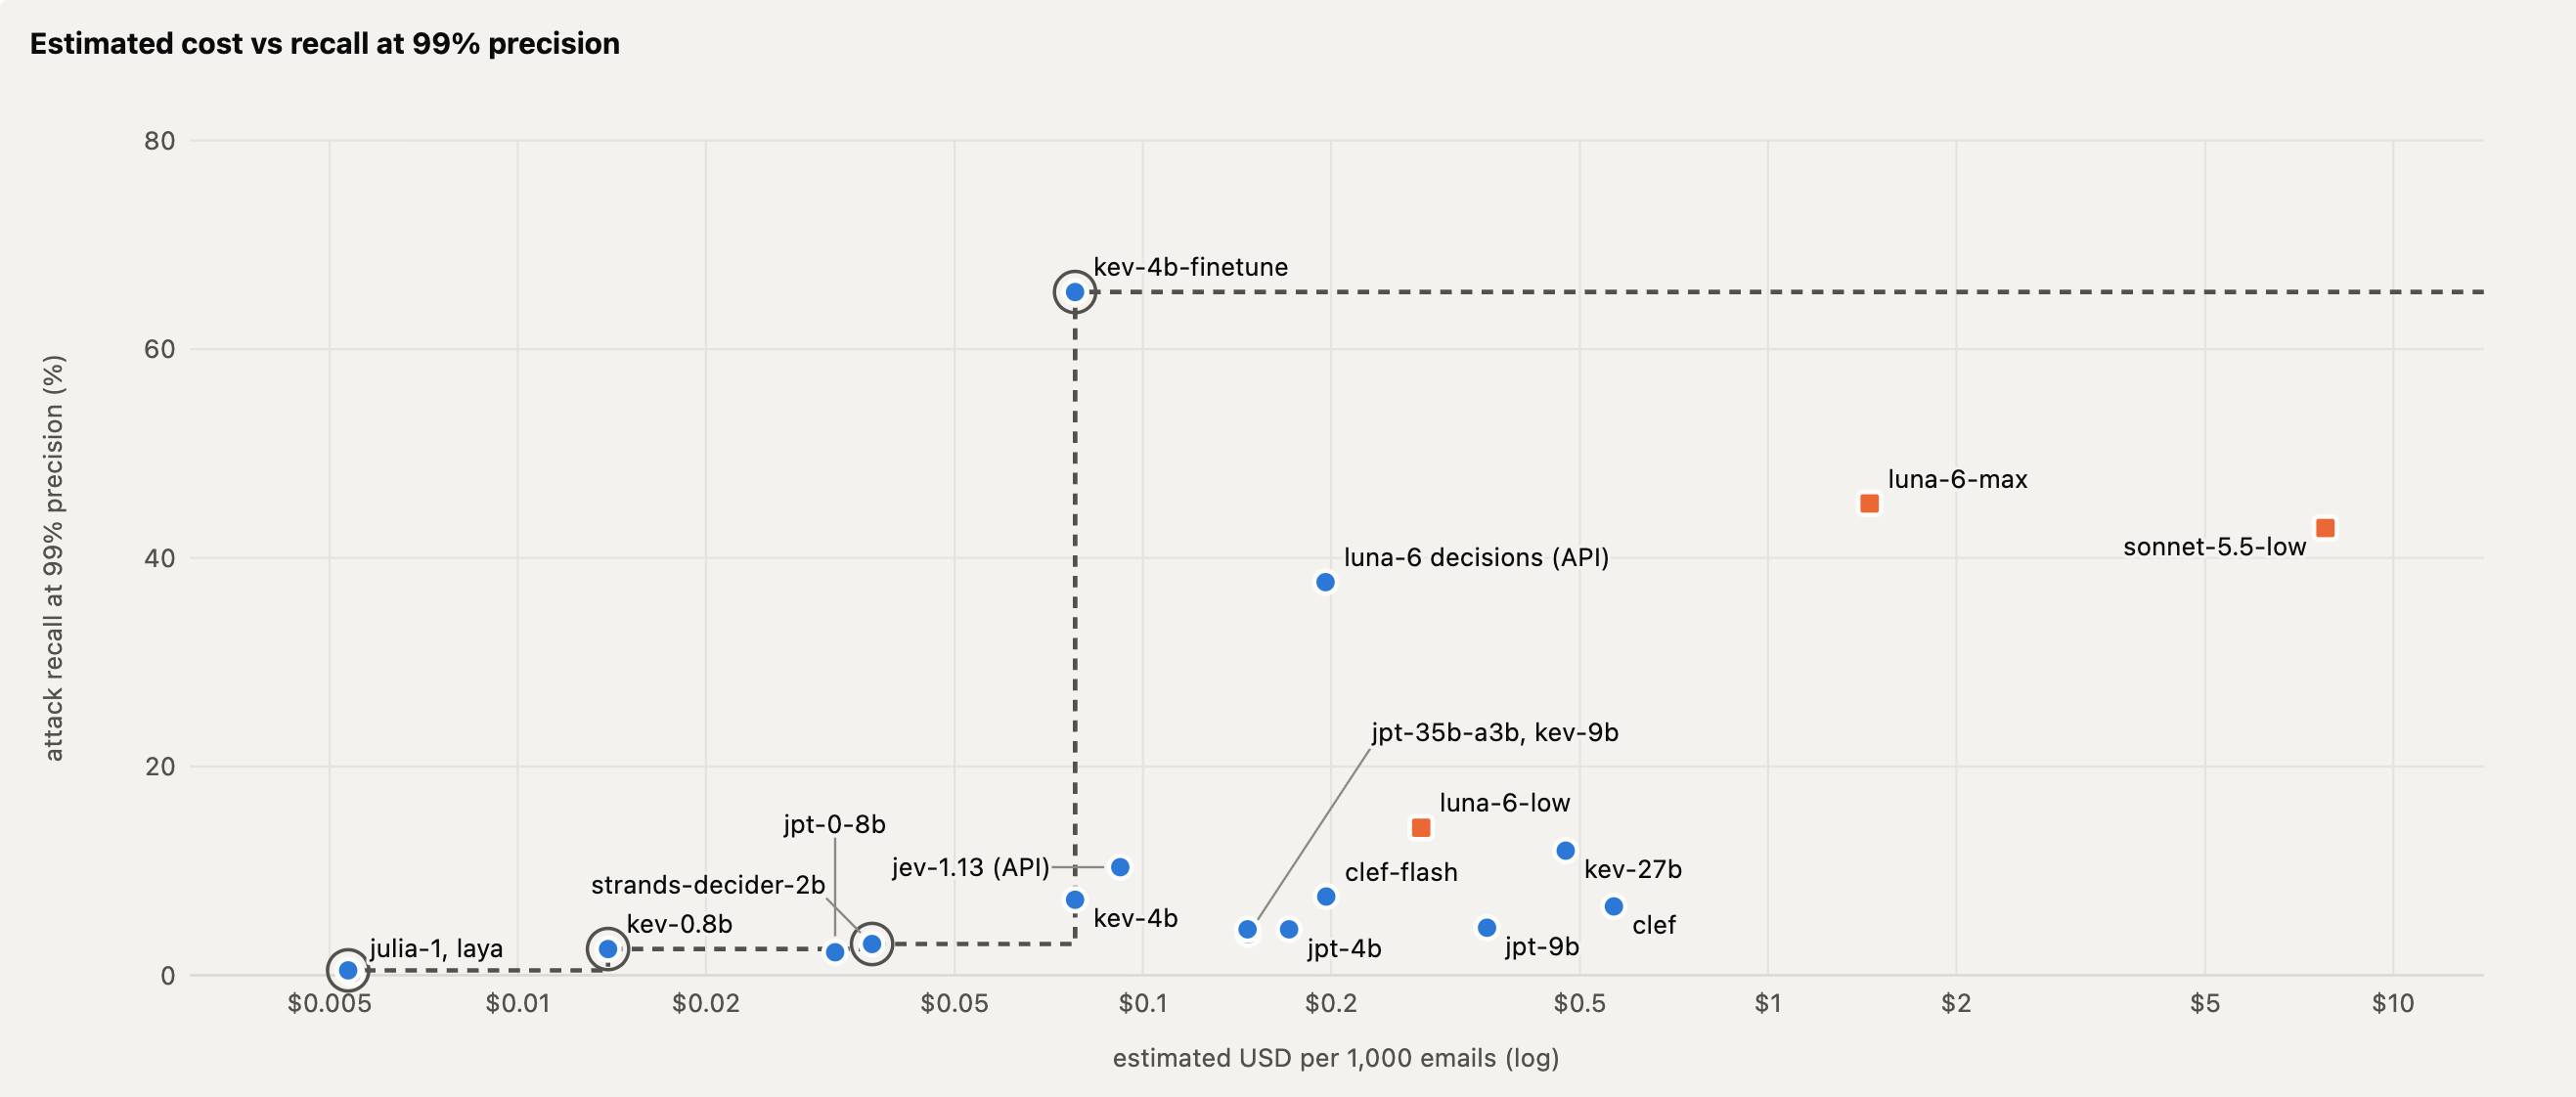
The fine-tune breaks the Pareto frontier, lifting recall at 99% precision from 7% to 66%, higher than any model we tested at any price5. Calibration improved with it, going from one of the worst in the field to among the best.
Attack-type macro-F1 fell from 68 to 37 in the same run, even as attack detection jumped, and the model now labels most BEC and recon emails as scams. Our training mix covered the four-way verdict but never attack types, so we suspect the fine-tune sharpened the question it was trained on and degraded one it wasn’t.
Inference
Training and evaluation leave out what it takes to serve a model online at our scale, which comes down to where it can run, what it really costs, and whether the GPUs exist.
Data residency. EU mail needs to be processed in the EU. An API only works if it can serve there, and a self-hosted fleet has to exist in every region we operate in, not just wherever GPUs are cheapest.
Real serving cost. The cost charts assume every GPU is busy all the time. Priced from kev-4b’s measured throughput in our harness at on-demand GPU rates, serving it costs more than the chart shows even with no idle time. Mail follows the workday and peaks need headroom, so actual utilization is lower and the cost higher still.
GPU supply. At our volume, running a 4B model on every email takes a GPU fleet that’s hard to get even with the budget for it.
Today, the equivalent detection in our online stack costs about a cent per thousand emails, on a mix of CPUs and GPU accelerators6. Decision models moved LLM-class judgment from dollars per thousand emails to cents and from seconds to milliseconds, which puts it within reach for the slice of traffic a prefilter sends them but not for every email.
We expect the right architecture at this scale to be a careful mix of model sizes and types, with cheap models on everything, decision models behind prefilters, frontier LLMs on the few emails that need real reasoning, and feedback loops that let the system improve itself.
If you want to help build it, we’re hiring.
We tested 40 models; the charts show the 18 most widely used and best performing. All open models were self-hosted for these evals and scored with their own reference inference code, on one L40S or, for the three largest, eight A100s.
Decision APIs: jev-1.13 (TypeSafe), luna-6 decisions (OpenAI Decisions API).
Frontier LLMs: sonnet-5.5 and luna-6, each at low and max reasoning effort. sonnet-5.5-max (email score 88.3, $52 per thousand emails) is left out of the charts. We wrote this post before haiku-5.5 came out and plan to evaluate it the same way.
Open decision models in the charts: kev-0.8b, kev-4b, kev-9b, kev-27b, jpt-0-8b, jpt-4b, jpt-9b, jpt-35b-a3b, clef, clef-flash, julia-1, laya, strands-decider-2b.
Open decision models not in the charts: bosun-0-6b, bosun-1-7b, clm-v0-1-8b, decider-2b, decider-4b, gliner-decide, hopper-g-1-2, intern-decision-0-8b, intern-decision-2b, intern-decision-4b, jet-v6-2, lavoir, lfm350-rlcd, lfm2600-rlcd, metask-jev-4b, neohorse-jev-4b, nimble-v2, pngwn-scorer-v2b, tev1-0-8b, this-that-1-2, winnow-12b-bf16.
Everything is measured on an 80% test split, with precision thresholds picked on that same split. The remaining 20% is held out to check how a threshold picked in advance holds up (note 5).
API models are priced at list rates on the tokens they used. Self-hosted decision models only prefill, so they're priced on input tokens at a typical hosted rate scaled by model size. The measured serving cost in Inference is our harness's throughput at on-demand GPU prices. Treat both as rough estimates, since idle capacity pushes real costs up while serving optimizations and committed-use discounts push them down.
An r256 LoRA on kev-4b, one epoch (7,500 steps), with the checkpoint picked by Brier score on a dev split. On our internal eval sets it also holds up on labels newer than its training data and on emails re-encoded as YAML, Markdown, or raw HTML.
We kept the comparison simple, but the 95% intervals overlap, so it would take more data to call this gap with confidence. Recall at 99% precision is 65.5% [49.8, 80.2] for the fine-tune and 49.9% [45.5, 83.2] for sonnet-5.5-max (bootstrap over 637 test attacks). With the threshold picked on the held-out split instead of the test set, the fine-tune still holds 98.6% precision at 67.7% recall. Precision is also computed as if half of all mail were attacks (the set itself is 40%), far above production rates, so read these numbers as relative.
Cloud cost (CPU and GPU) of the ML models in our real-time scoring path, divided by the emails they scored over the same recent window. It leaves out the rest of the pipeline (ingestion, parsing, storage, the portal) and offline training, all of which an LLM-based system would need too.